Arabic AI Newsroom Assistant with a 3-Agent Agentic Loop
 October, 2026
- By Ram Nimbalker
The Problem
Arabic newsrooms face a dual challenge:
- Speed pressure – Breaking news demands fast content turnaround
- Quality Control – AI-generated Arabic often lacks grammar, regional tone, and editorial standards.
- Accountability – No audit trail when AI content goes wrong
Most AI writing tools give you one draft and call it done.
Editors either accept flawed output or rewrite from scratch.
My Solution
I built a 3-agent agentic pipeline where AI critiques and refines its own work before presenting options to the editor.
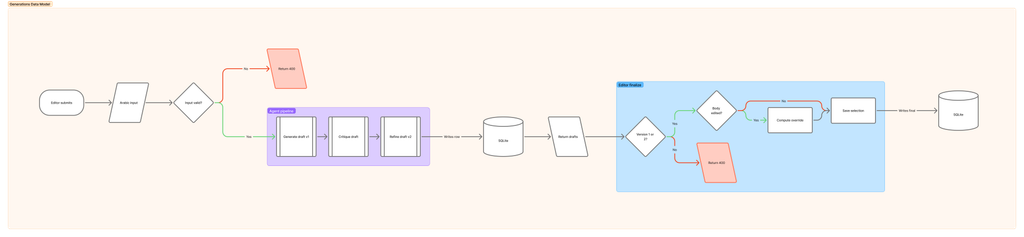
The Pipeline
Input: "ارتفاع أسعار النفط"
         ↓
🤖 AGENT 1: GENERATOR
   Creates Draft V1: 3 headline options, body, SEO, tags
         ↓
🔍 AGENT 2: CRITIC
   Reviews V1 section-by-section in Arabic
   Scores each section, flags issues
         ↓
✨ AGENT 3: REFINER
   Takes V1 + critique → produces improved Draft V2
         ↓
📊 EDITOR VIEW
   Side-by-side comparison: V1 vs V2
   Editor picks, edits, or overrides
         ↓
💾 AUDIT LOG
   Tracks: which version selected, what was edited, override %
Key Features
- Two Generation Modes
- Simple Mode
- Agentic Mode
- Arabic – First Design
- Right-to-left interface
- Arabic prompts and critique feedback
- Designed for Gulf newsroom standards
- Human-in-the-loop Governance
- Editor always has final say
- Override tracking: system logs when editors change AI output
- Override percentage calculated and stored
Full Audit Trail
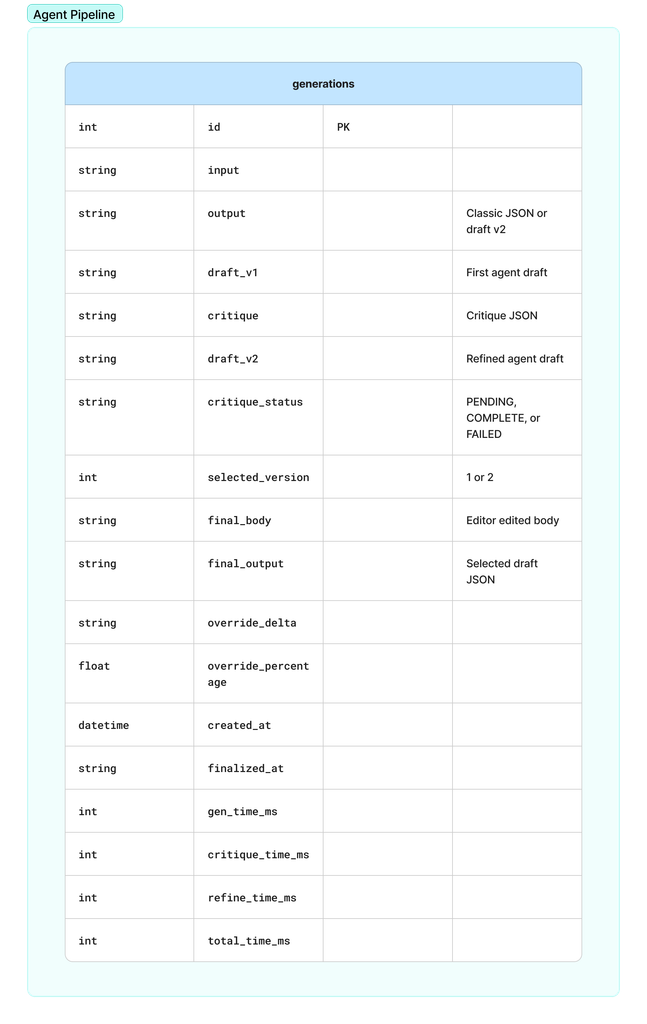
Every generation stores:
- Original Input
- Draft V1 (Generator output)
- Critique (Critic feedback with scores)
- Draft V2 (Refiner output)
- Selected version (1 or 2)
- Editor’s final body (if edited)
- Override delta and percentage
- Timing Metrics (gen_time_ms, critique_time_ms, refine_time_ms)
Archietecture
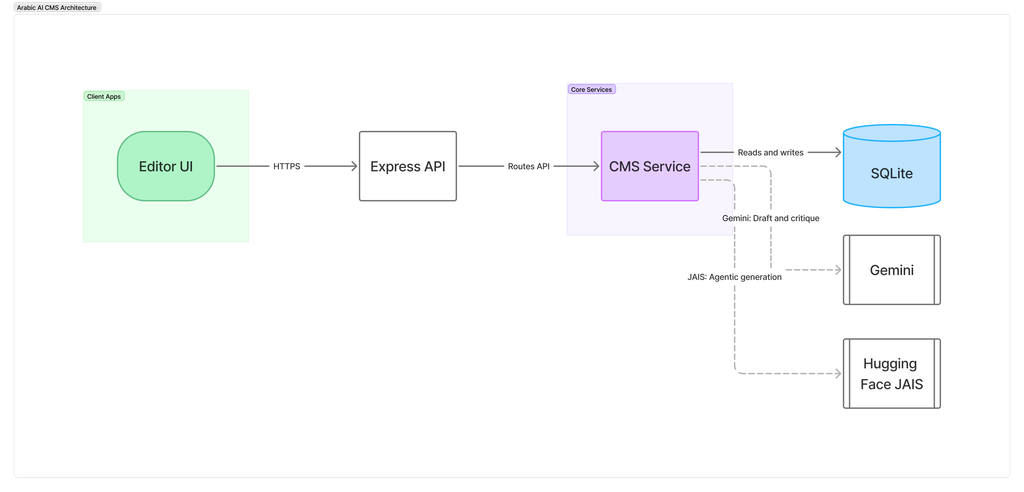
Tech Stack:
- Frontend: Vanilla JS, Tailwind CSS
- Backend: Node.js, Express
- Database: SQLite
- AI: Google Gemini 2.5 Flash (architected to swap to Jais Arabic LLM)
Why this Matters for Saudi Newsrooms
| Challenge | How this Solves it |
|---|---|
| AI makes grammar errors | Critic agent catches issues before editor sees them |
| No visibility into AI decisions | Full audit trail for every generation |
| Editors waste time fixing AI | V2 is already improved; editor reviews, not rewrites |
| Compliance concerns | Override tracking proves human oversight |
Screenshots
- Mode Toggle
- Agent Progress
- Critique Panel
- Side-by-side Comparison
(Screenshots to be added)
What I learned
- Agentic loops need structure – Without clear handoffs between agents, output degrades
- Arabic critique is harder – The critic prompt required careful tuning for proper Arabic Feedback
- Audit trails build trust – Editors adopted faster when they could see exactly what the AI changed
Links
- GitHub:
- Architecture Diagram
- Live Demo
Built With
- Node.js + Express
- SQLite
- Google Gemini 2.5 Flash
- Vanilla JS + Tailwind CSS
- Figma (architecture diagrams)
Part of myAI PM portfolio demonstrating agentic AI patterns for enterprise content workflows.